
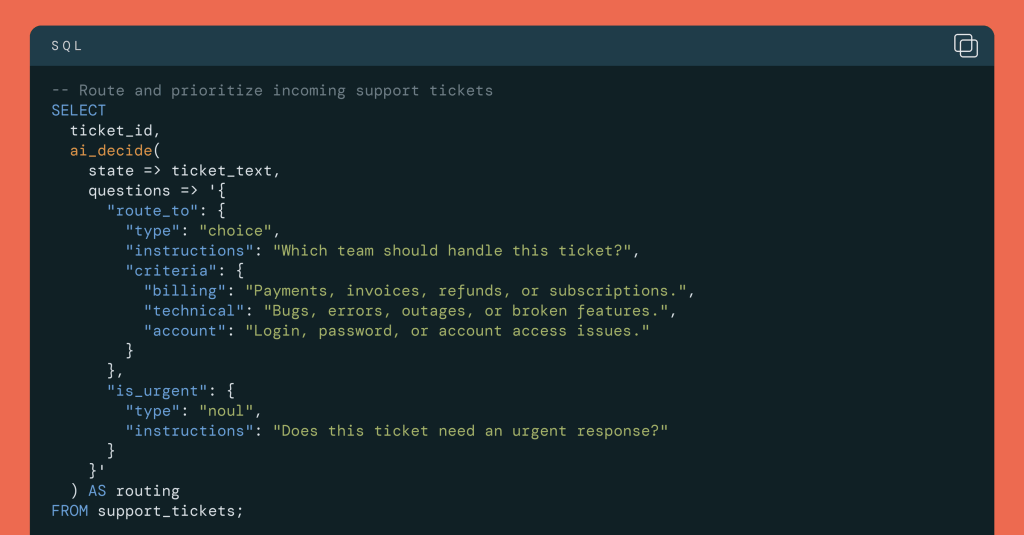
Happy friday folks.
So this one is a follow-on to a video I created on this a couple of weeks ago. It’s a bigger topic than a short explainer, so I felt a deeper walkthrough would be of interest.
The scenario: If you’ve built anything with LLMs over the last couple of years, you’ll know the feeling: you ask a model a yes/no question about a “thing” – say a support ticket – and you get back three polite paragraphs, a caveat and, eventually, the word “billing”. It works, but it’s a bit like asking for directions and getting someone’s life story.
A lot of what we actually ask AI to do on our data isn’t writing at all. It’s the small decisions: which team owns this, does it need to be escalated, how urgent is it? That’s exactly the job ai_decide was built for, and it’s now in Beta. This post is a bit of both worlds: first a look at the new class of model under the hood (and why it’s different to an LLM), then the fun stuff, a support-ticket triage demo you can run in your own workspace.
System One vs System Two (or, Why Not Just Use an LLM?)
For those who have read Daniel Kahneman’s Thinking, Fast and Slow, you’ll know the two systems: System 1 is fast and intuitive; System 2 is slow and deliberate. LLMs are very much System 2 machines. They reason by writing, one token after another, and that’s brilliant when you want an essay, a plan or some code.
TypeSafe AI, which builds the model behindai_decide, call their new class of model System One models, and their first public one is Jev. Their description is a nice one-liner:
“A frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.”
Right, so in plain English, here’s how it differs from an LLM (per TypeSafe’s post):
- It doesn’t write text — it generates its outputs in parallel rather than token by token, and hands back typed values, not a string you then have to parse.
- It can’t break the schema — TypeSafe report a 0% type-error rate. It can still give you the wrong answer, but you’ll never get “Sure! Here’s your JSON:” back in a column.
- It’s trained to be calibrated — rather than RLHF, Jev uses what they call RLCD (Reinforcement Learning for Calibrated Decisions). The idea is that a higher confidence really does mean a higher chance of being right.
- It’s built for speed and cost — TypeSafe quote 70–500 ms end to end, input tokens at $0.042 per million and output tokens free, and on their own workflow evals up to “193.6x faster, 444.6x cheaper” than frontier LLMs (they’re upfront that this is the higher end of real-world gains). Those are their numbers, not mine.
Interestingly, TypeSafe flip the usual reading of Kahneman: System 1 is normally the error-prone one, but they argue that for decisions like these a System One model can be more reliable than the alternatives.
Why This Is a Big Shift
Right, so why do I think this matters more than “another AI Function”? Because for the last couple of years the LLM has been the hammer for every nail. Need to classify a review? LLM. Route a ticket? LLM. Check an answer against policy? LLM. And our announcement blog puts its finger on the problem: for these small, structured decisions you’re “paying for additional latency and cost that compounds at enterprise scale”. One ticket is nothing. Millions of documents, every night, is a very different bill.
There are a few shifts in here, and they’re bigger together than apart:
- From generating to deciding — An LLM gives you text, and you turn it into a decision (parse the JSON, map the label, handle the “Sure! Here’s…”). A System One model gives you the decision itself, in a shape software can use directly. That sounds like a small thing until you’ve written the fifteenth
try_parse_jsonwrapper. - From “trust me” to “here’s how sure I am” — This is the big one for me. A calibrated probability turns uncertainty into a first-class output, so you can automate the confident 90% and send the rest to a person. That’s the difference between a demo and a process you’d let near real customers, and it’s exactly what the routing step later on is built on.
- From occasional to everywhere — When a decision is cheap and fast enough, it stops being a special AI job you batch up overnight and becomes something you call inline, like
UPPER()or aCASEstatement. Our blog’s examples hint at where that goes: tagging every product review, routing every prompt to the right model, judging every AI answer against policy, even deciding every move in a game of Snake. - System One and System Two — None of this makes LLMs redundant. The nice pattern is using each for what it’s good at: a decision model to triage, route and check, and an LLM for the bits that genuinely need reasoning or writing. Routing prompts to the right model is literally one of the launch use cases.
For those that know me and my warehouse years: we’ve been writing CASE WHEN body LIKE '%refund%' rules forever. They were fast, cheap and predictable, and they understood nothing. LLMs understood everything, but came back with an essay and a bill. This sits in between: a CASE statement that actually understands the text, and tells you how confident it is. That’s the bit that got me excited.
And that’s where the name comes in. Jev is named after William Stanley Jevons, the author of the Jevons paradox: when coal got more efficient to use, we didn’t use less of it; we used a lot more. TypeSafe’s bet is that machine intelligence goes the same way. Make a decision cheap and fast enough and you’ll start making it on every row, every event and every click (yes, yes, I know what people will say to that).
What Is ai_decide?
It would be remiss of me not to point you at the official ai_decide documentation and our announcement blog first. The short version: it’s a native AI Function that “takes unstructured text and returns structured decisions in a fraction of a second”, callable from SQL for batch work or through a REST API for real-time apps, and it’s directly compatible with the TypeSafe AI API.
The signature is refreshingly small:
ai_decide(state, questions [, options])
- state — the text (or JSON, or a VARIANT from another AI Function such as
ai_parse_document) to decide on. - questions — a constant JSON string. Each key is a question ID; each question has a
type, plain-Englishinstructionsand, depending on type, somecriteria. - options — optional; today the only one is
map('version', '1.0').
And there are three kinds of question:
noul— a probability from 0 to 1 that something is true (think “needs escalation?”).choice— pick one of up to 255 labels, with a probability per label and a confidence.score— an ordered scale of 2 to 10 steps; you get back a probability-weighted score (so 1.65 on a 0–2 scale is a real answer), plus a confidence.
It returns a VARIANT with response, metadata and error_message, so you pull the bits out with the usual : path syntax.
The Scenario
Support-ticket triage, the classic small-decision problem (and the one from the video). I’ve got a table of 40 fictional tickets: double charges, parcels left in the rain, production outages, a feature request, someone who just wants to say they love dark mode, and one that simply says “Hi, is anyone there?”. For every ticket I want:
- which team should handle it (billing, shipping, technical support or other),
- whether it needs escalating to a duty manager right now, and
- how urgent it is on a three-step scale.
Then I want to use those answers: route the confident ones automatically and send the unsure ones to a human.
Prerequisites
- A Unity Catalog-enabled Databricks workspace in a region that supports AI Functions
- A serverless or pro SQL warehouse (not Classic), or DBR 15.4 LTS+ (18.2+ recommended)
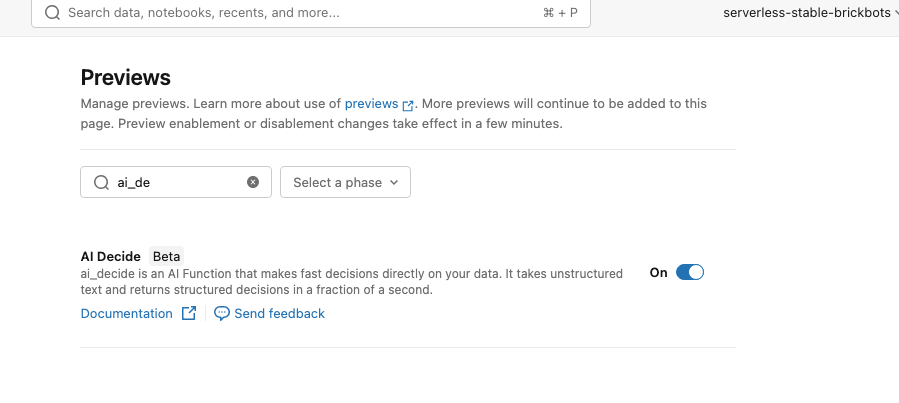
- The AI Decide preview switched on by a workspace admin — I forgot this bit and got a polite
PERMISSION_DENIED: AI Decide Preview is not enabledfor my troubles
- A catalog and schema you can create a table in. Mine’s
ai_decide_demo; swap in your own[your_catalog].[your_schema]throughout.
The setup script with all 40 tickets is a bit long to paste here, so it’s in the Appendix at the end; it’s just a CREATE TABLE and an INSERT with ticket_id, created_at, customer_tier, subject and body.
The Fun Stuff
1 – Write Your Questions
This is where all the work is, and it’s plain JSON. Each question gets a type, instructions and criteria:
{ "team": { "type": "choice", "instructions": "Which team should handle this support ticket?", "criteria": { "billing": "Payments, invoices, refunds, subscriptions and charges", "shipping": "Deliveries, parcels, couriers, customs and returns", "technical_support": "Product, app, API, login or device problems", "other": "Feedback, sales enquiries or anything none of the other teams handle" } }, "needs_escalation": { "type": "noul", "instructions": "Does this ticket need immediate escalation to a duty manager?", "criteria": { "true": "The customer is blocked from working, losing money, or facing a security risk right now.", "false": "The customer can carry on, has a workaround, or the request can wait." } }, "urgency": { "type": "score", "instructions": "How urgent is this ticket?", "criteria": [ "Routine request with no time pressure", "Time-sensitive, but the customer has a workaround", "Critical: blocks the customer or puts the business at risk" ] }}
Note the other label: always give a choice question somewhere to put the odd ones, or it’ll squeeze them into whichever team looks least wrong.
2 – One Ticket, Three Answers
Let’s try it on a single nasty one: an enterprise customer whose payment failed overnight and whose whole account has been suspended. (In the SQL below I’ve shortened the questions to '{ …questions… }' for readability; paste the full JSON from step 1 in its place.)
SELECT ticket_id, subject, ai_decide(body, '{ …questions… }') AS decisionFROM [your_catalog].[your_schema].ticketsWHERE ticket_id = 1010;
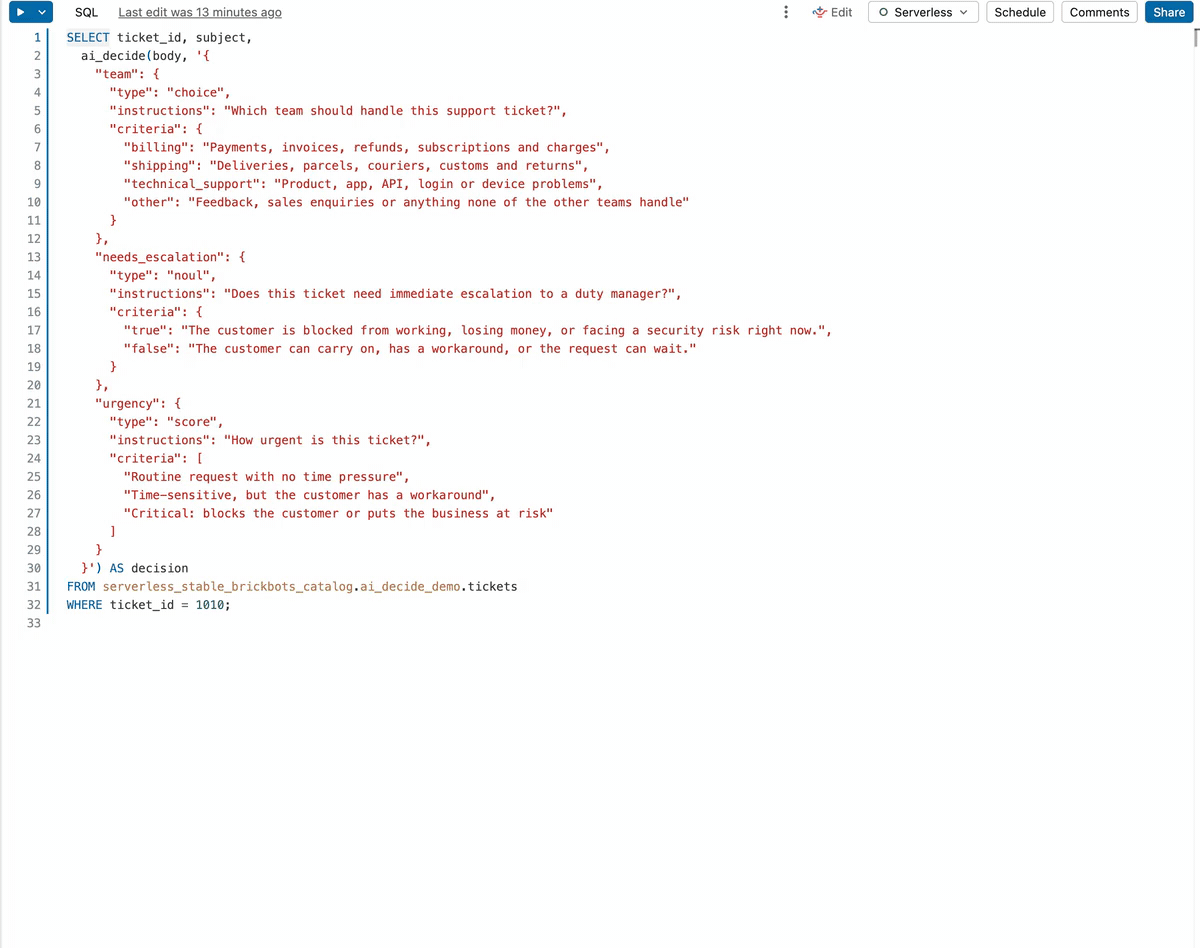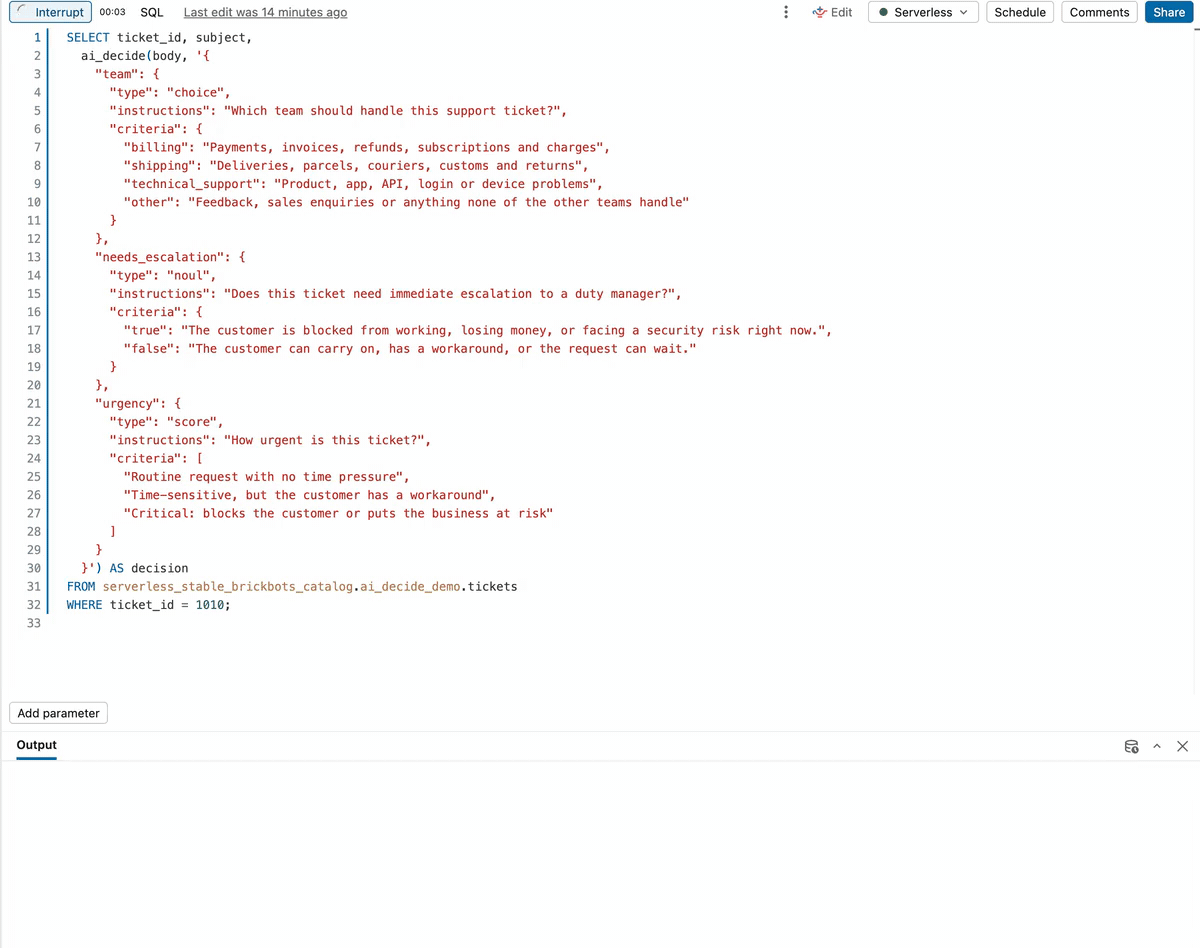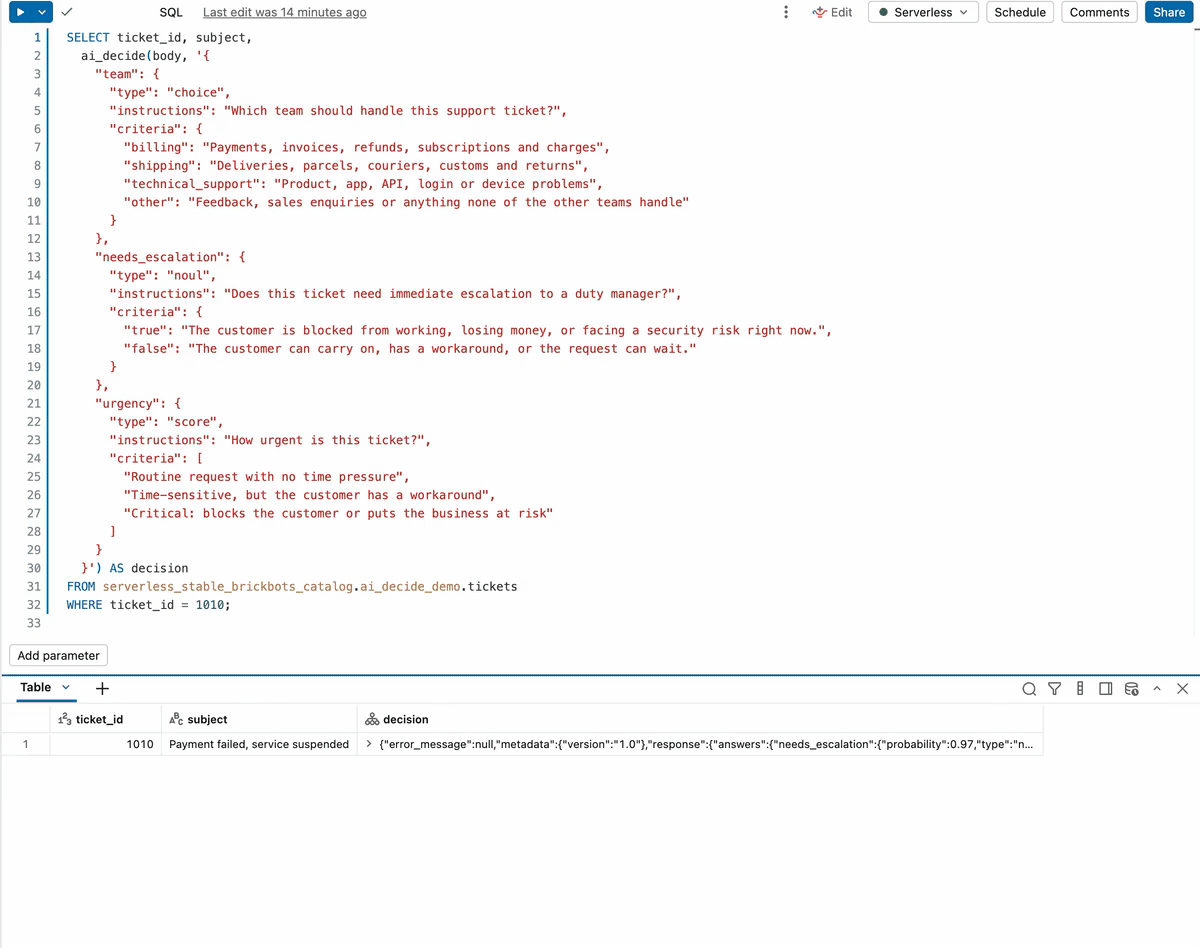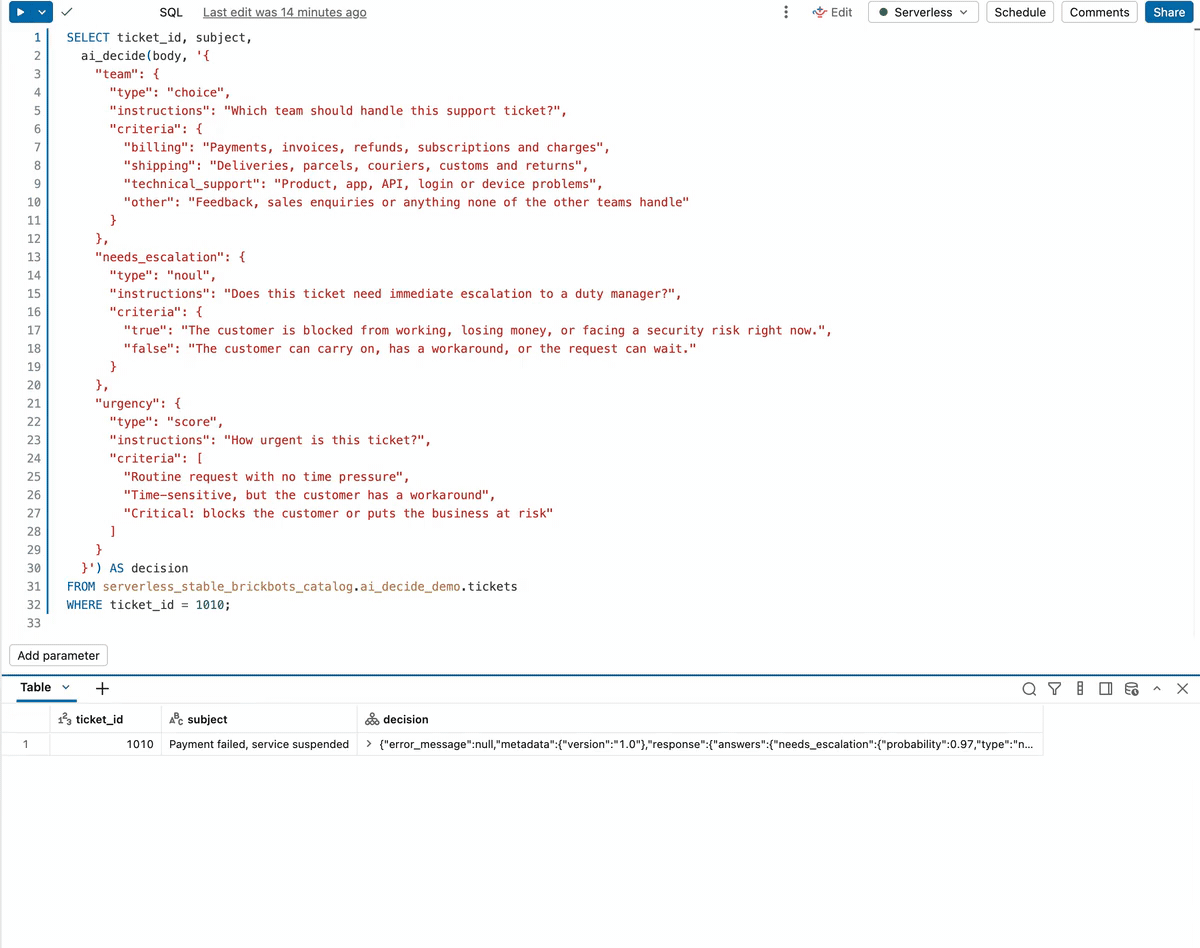
And low and behold, one call, three answers:
{ "response": { "answers": { "team": { "type": "choice", "choice": "technical_support", "confidence": 0.95, "probabilities": { "billing": 0, "other": 0, "shipping": 0, "technical_support": 1 } }, "needs_escalation": { "type": "noul", "probability": 0.97 }, "urgency": { "type": "score", "score": 1.9000000000000001, "confidence": 0.96, "probabilities": { "0": 0, "1": 0.1, "2": 0.9 }, "legend": { "0": "Routine request with no time pressure", "1": "…", "2": "…" } } } }, "metadata": { "version": "1.0" }, "error_message": null}
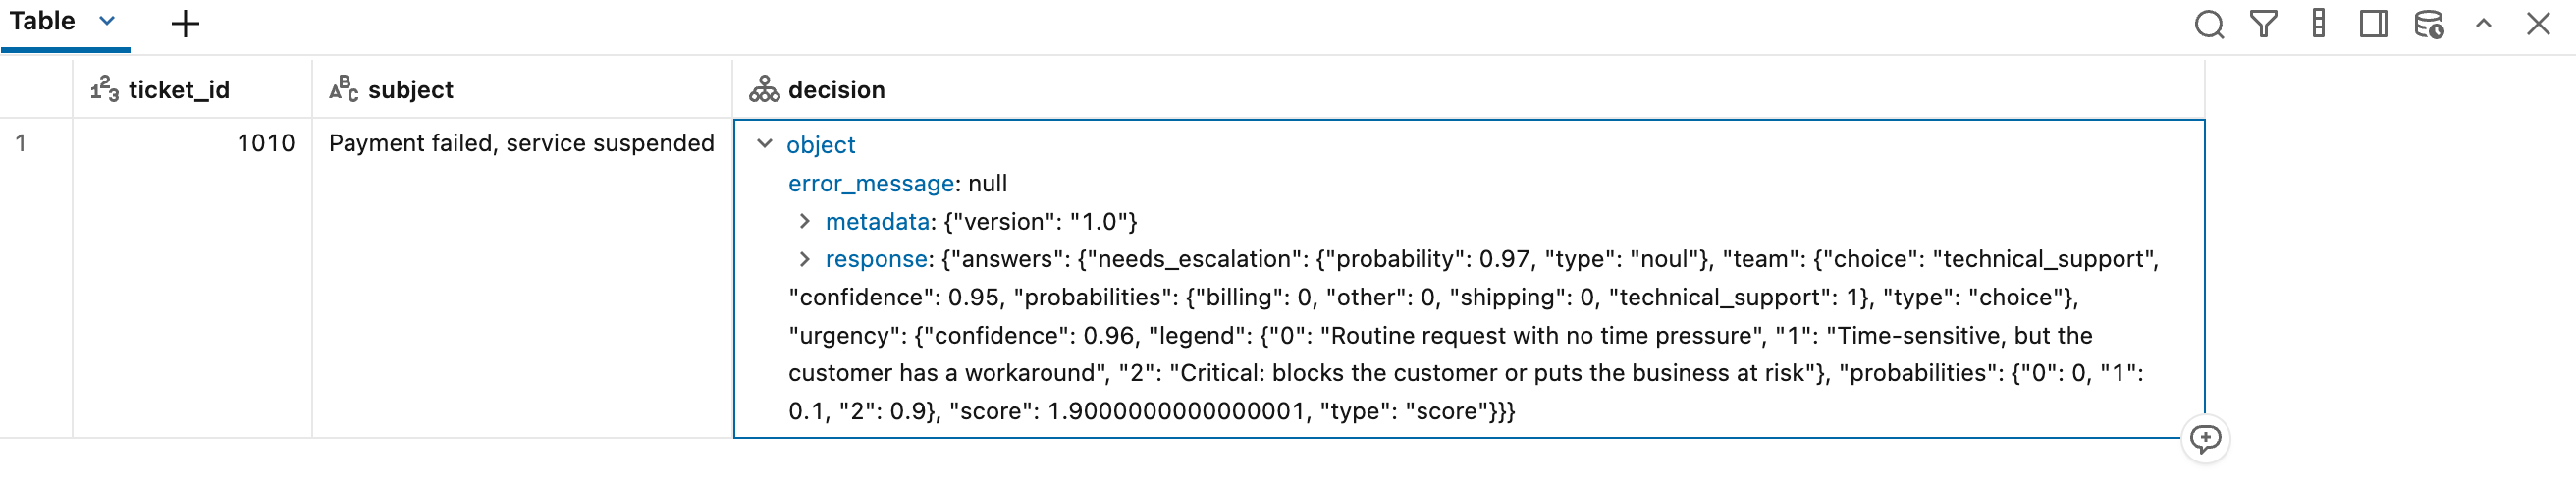
(I’ve trimmed the legend, and yes, that’s a floating-point 1.9 — round it in your query.) Almost certainly an escalation, critical on the urgency scale, and… technical support? Hmm. You could argue it either way: the account is suspended (a tech problem) because a payment failed (a billing one). Keep an eye on this one; it comes back later. No prompt, no output parsing, no “please respond only in JSON” pleading, though.
3 – Decide the Whole Table (Once)
Now the whole table. One golden rule with any AI Function: run it once and persist the result, then query the cheap Delta table as much as you like.
CREATE OR REPLACE TABLE [your_catalog].[your_schema].ticket_decisions ASSELECT ticket_id, customer_tier, subject, body, ai_decide(body, '{ …questions… }') AS dFROM [your_catalog].[your_schema].tickets;SELECT ticket_id, subject, d:response.answers.team.choice::string AS team, round(d:response.answers.team.confidence::double, 2) AS team_confidence, round(d:response.answers.needs_escalation.probability::double, 2) AS p_escalate, round(d:response.answers.urgency.score::double, 2) AS urgencyFROM [your_catalog].[your_schema].ticket_decisionsORDER BY ticket_id;
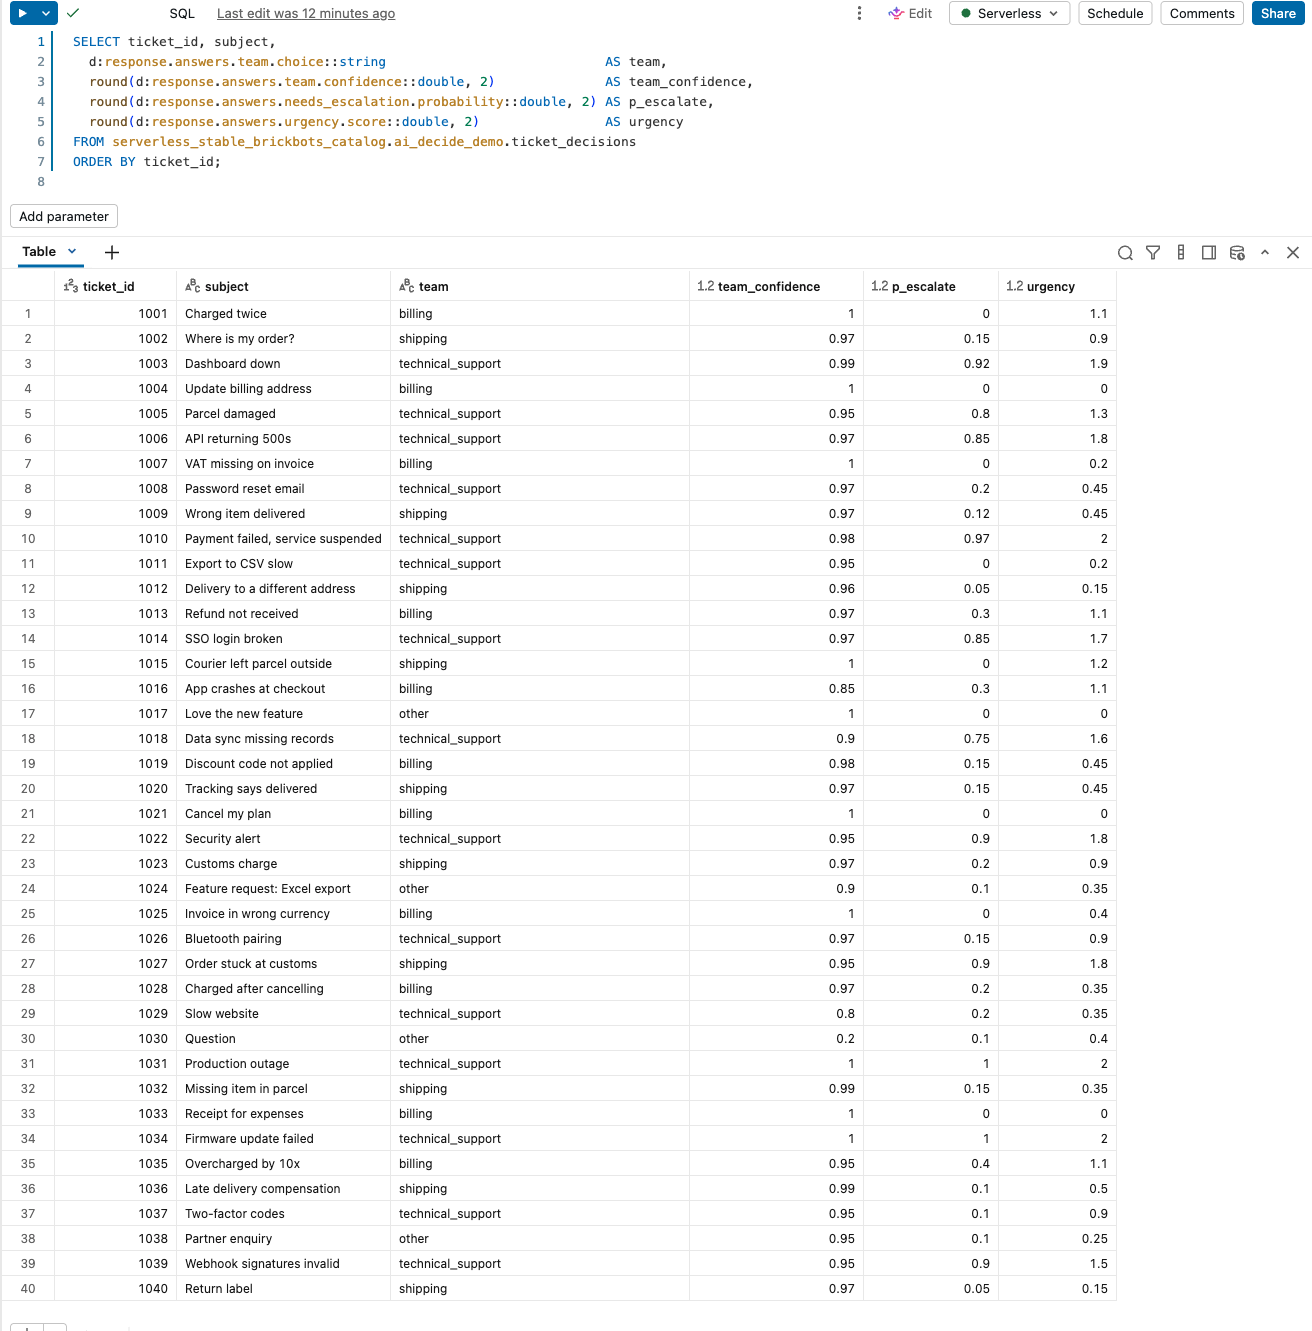
Mostly spot on. “Production outage” and “Firmware update failed” come out at an escalation probability of 1.0 and urgency 2, “Update billing address” at 0 and 0, and “Hi, is anyone there?” gets other with a confidence of just 0.2. That’s the model saying I’m guessing here, which is exactly what you want it to say. Hold that thought.
4 – How Does That Compare to an LLM?
To be fair to the LLMs I ran the same triage through ai_query with two models from our Foundation Model APIs, a small one (Claude Haiku 4.5) and a bigger one (Claude Sonnet 4.5), using a strict JSON schema so they had to answer in the same shape:
CREATE OR REPLACE TABLE [your_catalog].[your_schema].ticket_decisions_llm ASSELECT ticket_id, subject, ai_query( 'databricks-claude-haiku-4-5', concat('You triage customer support tickets. Answer in JSON. ', '…the same team, escalation and urgency definitions as step 1… ', 'Ticket: ', body), responseFormat => '{"type":"json_schema","json_schema":{"name":"triage","strict":true,"schema":{"type":"object","properties":{"team":{"type":"string","enum":["billing","shipping","technical_support","other"]},"needs_escalation":{"type":"boolean"},"urgency":{"type":"integer","enum":[0,1,2]}},"required":["team","needs_escalation","urgency"],"additionalProperties":false}}}', failOnError => false ) AS rFROM [your_catalog].[your_schema].tickets;
I’ve trimmed the prompt here; it just restates the definitions from step 1. On which team, all three mostly agreed; they only differed on three tickets (more on one of those shortly). The interesting bit is escalation:
SELECT (SELECT count_if(d:response.answers.needs_escalation.probability::double >= 0.8) FROM [your_catalog].[your_schema].ticket_decisions) AS ai_decide_over_0_8, (SELECT count_if(get_json_object(r.result, '$.needs_escalation') = 'true') FROM [your_catalog].[your_schema].ticket_decisions_llm) AS llm_says_true;
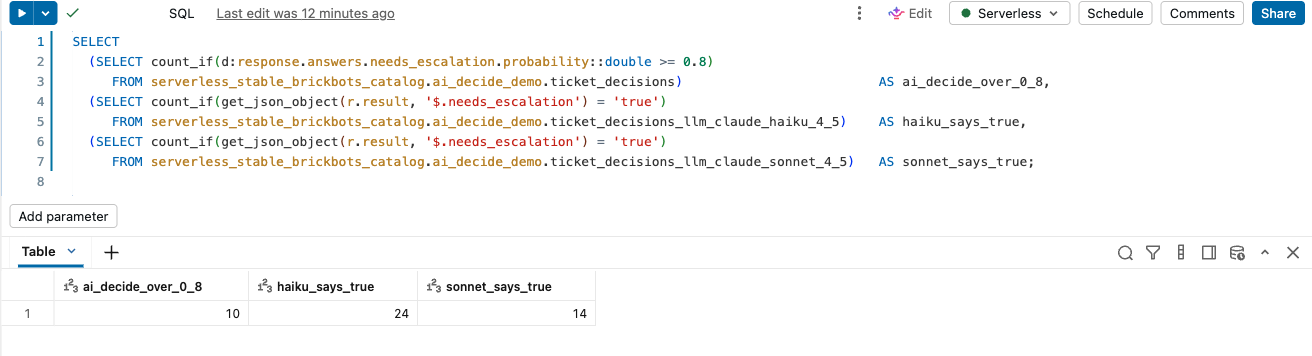
Haiku wanted to escalate 24 of the 40 tickets (including a discount code that didn’t apply and an invoice in the wrong currency), Sonnet 14, and ai_decide at a 0.8 threshold 10. Now, you could argue about which is “right”, and you could absolutely tune the LLM prompt. But that’s the point: with the LLM you get a yes or a no, and your only lever is rewriting the prompt. With ai_decide you get a probability, and the threshold is a number you choose in a WHERE clause. Busy Monday? Raise it. Quiet Friday? Lower it. Same results table, no re-run.
5 – Route on Confidence
This is the bit I’m most excited about. Because every answer comes with a probability and a confidence, routing is just a CASE statement:
CREATE OR REPLACE VIEW [your_catalog].[your_schema].ticket_routing ASSELECT ticket_id, customer_tier, subject, d:response.answers.team.choice::string AS team, d:response.answers.team.confidence::double AS team_confidence, d:response.answers.needs_escalation.probability::double AS p_escalate, CASE WHEN d:error_message::string IS NOT NULL THEN 'human_review' WHEN d:response.answers.needs_escalation.probability::double >= 0.8 THEN 'duty_manager' WHEN d:response.answers.team.confidence::double < 0.8 THEN 'human_review' ELSE concat('queue_', d:response.answers.team.choice::string) END AS routeFROM [your_catalog].[your_schema].ticket_decisions;SELECT route, count(*) AS ticketsFROM [your_catalog].[your_schema].ticket_routingGROUP BY route ORDER BY tickets DESC;
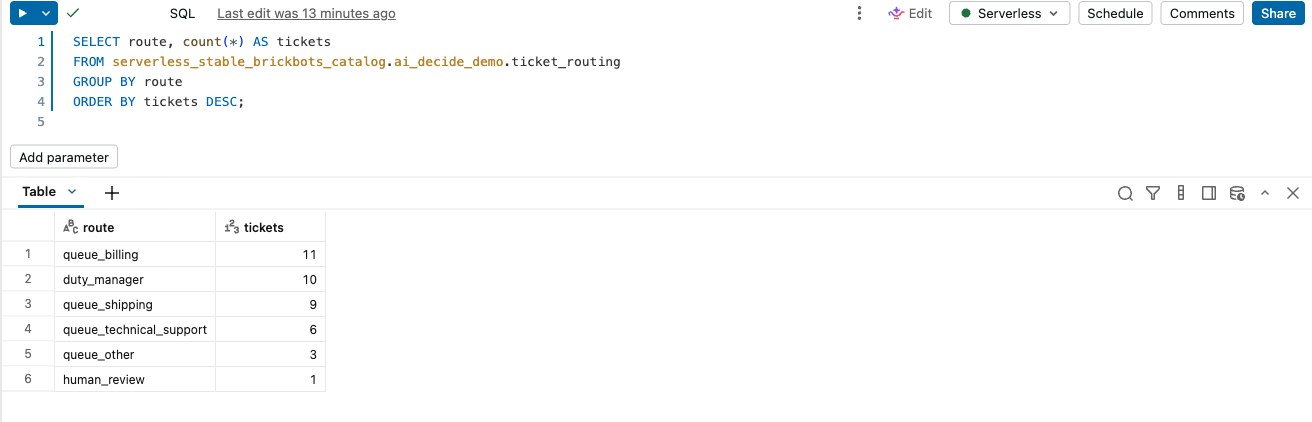
Ten tickets go straight to the duty manager (outages, the security alert, the pallet stuck at customs before a store opening), one goes to a human (our friend “Hi, is anyone there?”), and the other 29 land in their team queues. Awesome beans.
Bot note: VARIANT null isn’t SQL NULL — My first version had WHEN d:error_message IS NOT NULL and sent all 40 tickets to human review. A JSON null inside a VARIANT is still a value, so that check is always true. Cast it first: d:error_message::string IS NOT NULL.
6 – When It’s Confidently Wrong
Right, the honest bit. Ticket 1005 says “The box arrived crushed and the screen on the device is cracked.” That’s a shipping problem (someone needs to send a replacement), but ai_decide put it in technical support with a confidence of 0.95, and both LLMs got it right. Calibration is about the averages; it doesn’t mean every confident answer is correct.
My first fix was to tighten the criteria (adding “including items damaged, missing or wrong on arrival” to shipping). It didn’t budge. What worked was putting the routing rule in the instructions, because the question was really who has to act next, not what’s the ticket about:
"team": { "type": "choice", "instructions": "Which team should handle this support ticket? Route by who has to act next: anything that arrived damaged, missing or wrong goes to shipping, who arrange the replacement, even if the item itself is a device.", "criteria": { "…": "as before" }}
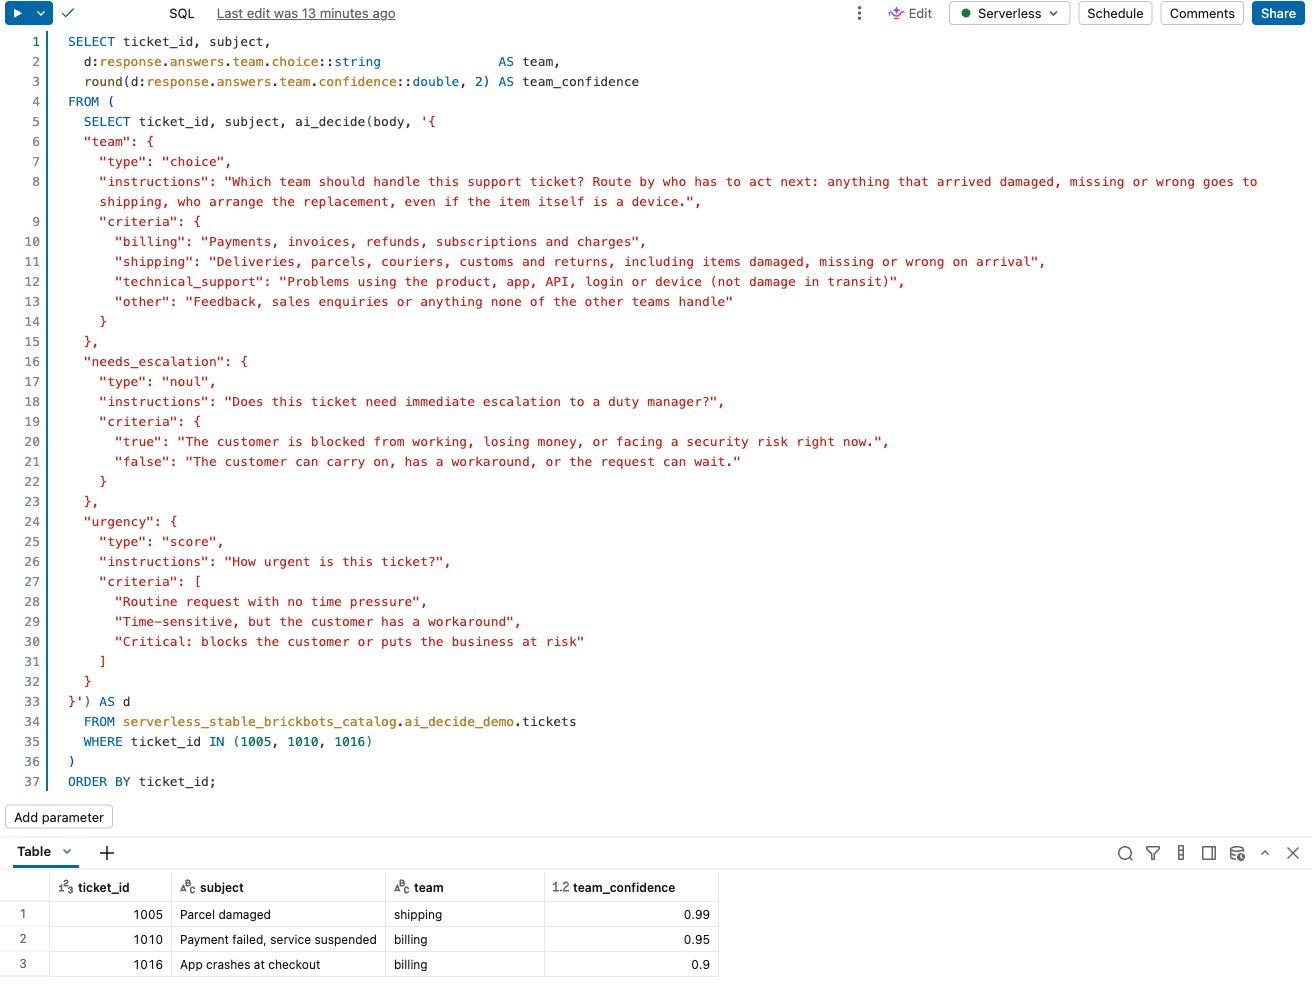
Bingo: shipping, 0.99. And our old friend 1010 (“Payment failed, service suspended”) settled on billing at 0.95, along with “App crashes at checkout”, which makes sense once the rule is “who has to act next”. Treat your questions like code: test them on the awkward rows, tweak, re-run.
Tips and Gotchas
- Answers can vary between calls — The docs say so, and I saw it: ticket 1010 has come back as billing in one run and technical support in another. Persist the results and decide on them once, rather than re-asking every query.
- Always have an escape hatch — An
otherlabel for choice questions, and a confidence threshold that sends anything unsure to a person. - Use instructions for rules, criteria for definitions — Criteria describe what each label means; instructions are where how to decide goes.
- Expect confident probabilities — On clear-cut tickets the choice probabilities were often a straight 1 and 0s. The confidence and the noul probability were the more useful dials.
- It’s Beta — The docs note the models may change, so don’t hard-code thresholds and forget about them.
Conclusion
That’s pretty much it. Hopefully this has shown where a decision model fits: not as a replacement for LLMs, but for the thousands of small, structured calls we’ve been paying an LLM to write essays about. The real win for me wasn’t the JSON or the SQL, it was getting a probability back, because that turns “the AI decided” into “the AI decided, and here’s how sure it was”, which is something you can actually build a process on.
This post only scratched the surface: I haven’t touched the REST API for real-time use (the Snake demo in our blog is worth a look), chaining it after ai_parse_document, or using it as a judge over other AI outputs. Watch this space.
As always, let me know your thoughts (and other ideas, of course!).
Useful Links
- ai_decide SQL reference
- Introducing ai_decide: make fast decisions on your governed data (Databricks blog)
- Introducing System One models and Jev (TypeSafe AI)
- AI Functions on Databricks
- ai_query function
Appendix: Setup Script
The 40 fictional tickets used throughout, if you want to follow along (swap in your own catalog and schema):
-- Hand-written, fictional tickets. A few are deliberately ambiguous (billing vs technical,-- or nothing to do with any team) so the confidence-routing step has something to catch.CREATE SCHEMA IF NOT EXISTS [your_catalog].[your_schema]COMMENT 'Demo data for the ai_decide blog post (SQL of the North / BrickBots)';CREATE OR REPLACE TABLE [your_catalog].[your_schema].tickets ( ticket_id INT, created_at TIMESTAMP, customer_tier STRING, subject STRING, body STRING);INSERT INTO [your_catalog].[your_schema].tickets VALUES(1001, '2026-10-12 08:02:00', 'enterprise', 'Charged twice', 'Our invoice for October has been charged twice to the company card. Finance need one of the payments reversed before month end.'),(1002, '2026-10-12 08:15:00', 'standard', 'Where is my order?', 'I ordered a replacement router nine days ago and the tracking page has not updated since it left the warehouse. Any idea where it is?'),(1003, '2026-10-12 08:31:00', 'enterprise', 'Dashboard down', 'None of our team can log in to the analytics dashboard since 7am. We get a 503 error on every page and our morning operations review is blocked.'),(1004, '2026-10-12 08:47:00', 'standard', 'Update billing address', 'We have moved offices. Please can you update the billing address on our account for future invoices? No rush.'),(1005, '2026-10-12 09:05:00', 'standard', 'Parcel damaged', 'The box arrived crushed and the screen on the device is cracked. I would like a replacement sent out please.'),(1006, '2026-10-12 09:20:00', 'enterprise', 'API returning 500s', 'Our nightly integration is failing. The orders API has returned HTTP 500 for every call since the release last night and we cannot process customer orders.'),(1007, '2026-10-12 09:41:00', 'standard', 'VAT missing on invoice', 'The latest invoice does not show our VAT number, which our accounts team needs for reclaiming. Can you reissue it?'),(1008, '2026-10-12 10:03:00', 'standard', 'Password reset email', 'I requested a password reset an hour ago but the email never arrived. I have checked spam. I can still use the mobile app in the meantime.'),(1009, '2026-10-12 10:22:00', 'standard', 'Wrong item delivered', 'I ordered the large size and received the small one. How do I swap it?'),(1010, '2026-10-12 10:40:00', 'enterprise', 'Payment failed, service suspended', 'Our card payment failed overnight and now the whole account has been suspended. Three hundred staff cannot work. Please restore access urgently, we will pay by bank transfer today.'),(1011, '2026-10-12 11:02:00', 'standard', 'Export to CSV slow', 'Exporting a report to CSV takes about five minutes now. It used to be quicker. It does finish, so not urgent, just annoying.'),(1012, '2026-10-12 11:18:00', 'standard', 'Delivery to a different address', 'Can I change the delivery address for order 55812? It has not been dispatched yet according to the website.'),(1013, '2026-10-12 11:35:00', 'standard', 'Refund not received', 'You confirmed my refund two weeks ago but the money has still not appeared in my account.'),(1014, '2026-10-12 11:52:00', 'enterprise', 'SSO login broken', 'Since we rotated our identity provider certificate nobody can sign in through single sign-on. Local admin accounts still work so a couple of us can get in.'),(1015, '2026-10-12 12:10:00', 'standard', 'Courier left parcel outside', 'The courier left my parcel in the rain outside the front door and the packaging is soaked. Contents seem fine though.'),(1016, '2026-10-12 12:31:00', 'standard', 'App crashes at checkout', 'Every time I try to pay for my subscription upgrade in the app it crashes on the payment screen. Is my card the problem or the app?'),(1017, '2026-10-12 12:50:00', 'standard', 'Love the new feature', 'Just wanted to say the new dark mode is brilliant. Keep it up!'),(1018, '2026-10-12 13:07:00', 'enterprise', 'Data sync missing records', 'The overnight sync to our warehouse is missing roughly 10 percent of yesterday''s records. Reports still run but the numbers are wrong for the board pack due tomorrow.'),(1019, '2026-10-12 13:25:00', 'standard', 'Discount code not applied', 'I entered the code AUTUMN20 at checkout but I was charged full price. Please refund the difference.'),(1020, '2026-10-12 13:44:00', 'standard', 'Tracking says delivered', 'Tracking says the parcel was delivered yesterday at 2pm but nothing has arrived and my neighbours have not seen it.'),(1021, '2026-10-12 14:02:00', 'standard', 'Cancel my plan', 'Please cancel my subscription at the end of this billing period. Thanks.'),(1022, '2026-10-12 14:20:00', 'enterprise', 'Security alert', 'We have spotted logins to our admin account from an unknown country in the last hour. Please help us lock the account down immediately.'),(1023, '2026-10-12 14:41:00', 'standard', 'Customs charge', 'The courier is asking me to pay a customs charge before they will deliver. I thought shipping was all-inclusive?'),(1024, '2026-10-12 15:00:00', 'standard', 'Feature request: Excel export', 'Would be great if reports could be exported straight to Excel rather than CSV. Any plans?'),(1025, '2026-10-12 15:18:00', 'standard', 'Invoice in wrong currency', 'Our invoices are coming through in US dollars but we are billed in pounds. Can this be corrected?'),(1026, '2026-10-12 15:36:00', 'standard', 'Bluetooth pairing', 'The device will not pair with my phone over Bluetooth. I have tried restarting both. The wired connection works fine.'),(1027, '2026-10-12 15:55:00', 'enterprise', 'Order stuck at customs', 'A pallet of 200 units for our store opening on Saturday has been held at customs for four days. If it does not arrive by Friday the opening is at risk.'),(1028, '2026-10-12 16:12:00', 'standard', 'Charged after cancelling', 'I cancelled last month but I was charged again this month. I would like a refund.'),(1029, '2026-10-12 16:30:00', 'standard', 'Slow website', 'The website feels a bit sluggish this afternoon. Pages take a few seconds to load.'),(1030, '2026-10-12 16:47:00', 'standard', 'Question', 'Hi, is anyone there?'),(1031, '2026-10-13 08:05:00', 'enterprise', 'Production outage', 'Our production environment is completely down. Every user is seeing a blank screen and we are losing sales every minute.'),(1032, '2026-10-13 08:22:00', 'standard', 'Missing item in parcel', 'The parcel arrived but one of the three items on the packing slip is missing.'),(1033, '2026-10-13 08:40:00', 'standard', 'Receipt for expenses', 'Can you send me a VAT receipt for my last payment so I can claim it on expenses?'),(1034, '2026-10-13 08:58:00', 'standard', 'Firmware update failed', 'The firmware update stopped at 60 percent and now the device restarts in a loop. I cannot use it at all.'),(1035, '2026-10-13 09:15:00', 'enterprise', 'Overcharged by 10x', 'This month''s invoice is ten times our usual amount. Something is clearly wrong with the usage figures. Please hold the direct debit until it is investigated.'),(1036, '2026-10-13 09:33:00', 'standard', 'Late delivery compensation', 'My next-day delivery took four days. Am I entitled to a refund of the delivery charge?'),(1037, '2026-10-13 09:50:00', 'standard', 'Two-factor codes', 'I am not receiving two-factor codes by text any more. I have a backup code so I can get in for now.'),(1038, '2026-10-13 10:08:00', 'standard', 'Partner enquiry', 'We are a reseller in Leeds and would like to talk to someone about a partnership.'),(1039, '2026-10-13 10:25:00', 'enterprise', 'Webhook signatures invalid', 'Since this morning every webhook you send fails our signature check, so payment confirmations are not reaching our system and customers are not getting their orders.'),(1040, '2026-10-13 10:44:00', 'standard', 'Return label', 'Could you email me a returns label? I want to send back the jacket I bought last week.');


Leave a Reply